I kind of loved BonziBuddy. You remember him? The purple monkey that everyone knew was malware of some kind, or at least had the feeling? AI agents have made a bit of a resurgence of the concept. "Desktop buddies", most harnesses now have at least a plugin to add them. They're cute, I guess, but in the 30 years since BonziBuddy you would have thought they would be better. They're still just IFTTT trees of prerendered animations. Live2D is a better solution, very much a child of the 2010s technologically speaking. Live2D is essentially the final-form of a paper doll. You have a rigged skeleton and 2d planes that move about that very convincingly generate animations. This is the tech behind "vtubers". Live2D is not enough.
Bonsai is an approach that is 2020s-native, that is to say, my focus is on emergent behavior. I want not to know what this little guy is going to do, or how.
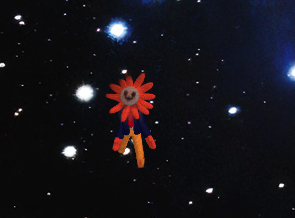
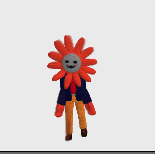
The Bonsai character is defined as a volume of neural cellular automata within a bounded rendering volume, that has a pose/body control vector derived from an intent-space, which itself is derived from embedding whatever some token predictor has said (not necessarily an LLM, but practically I mean an LLM). This project is not complete, though it is on the right track I think- the NCAs must be trained, and right now I'm bootstrapping their training off of 3D models in different poses. The intent vector then moves the pose control vector through the pose space to generate animations. It looks pretty wild.
In an ideal world, that pose vector would also have greater definitional control over the self-expression of the NCA field, that is to say, the NCAs wouldn't be trained on a single model, they would be trained on many many forms, and could generate their own self-representation based on how the LLM was acting. Like I said, emergent behavior.
The Claudeguys pictured below use an original 3D model from anima-research/eidoverse-worlds.